Python实现网页高频词提取

1. 网页文本提取
import re
def clear_text(text: str) -> str:
    # 去除HTML标签
    text = re.sub('<.*?>', '', text)
    # 去除多余空格
    text = re.sub('\s+', '', text)
    return text.strip()

# 函数调用
html_text = '''<p><span style="font-family: Arial, sans-serif; font-size: 20px; color: #0066cc;">
    <div>这是一个   测试文本</div>
</span></p>'''
clear_text = clear_text(html_text)
print(clear_text)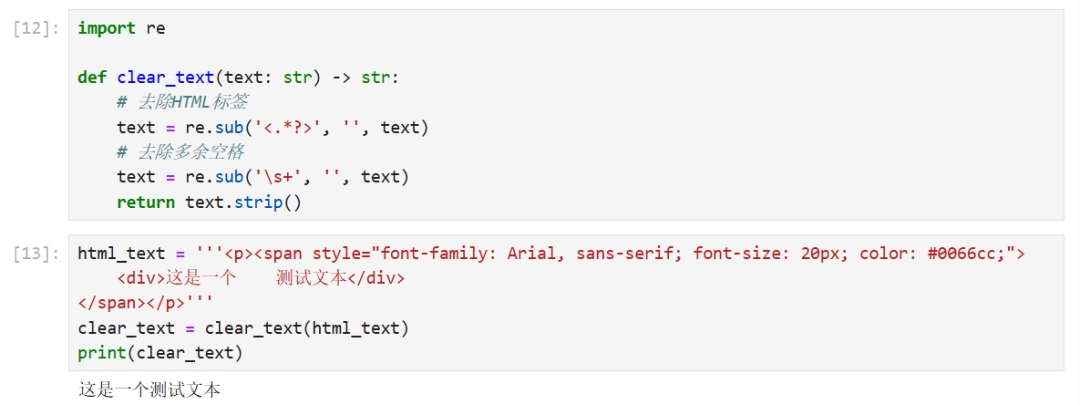
2. 文本词频统计
import jieba
from collections import Counter
text = "本周进行自然语言处理系列文档示例,示例围绕自然语言处理程序。"
words = jieba.cut(text)
words_list = list(words)
words_count = Counter(words_list)
words_filter = [word for word, count in words_count.items() if count > 1]
print("分词结果:", words_list)
print("词频:", words_count)
print("高频词汇:", words_filter)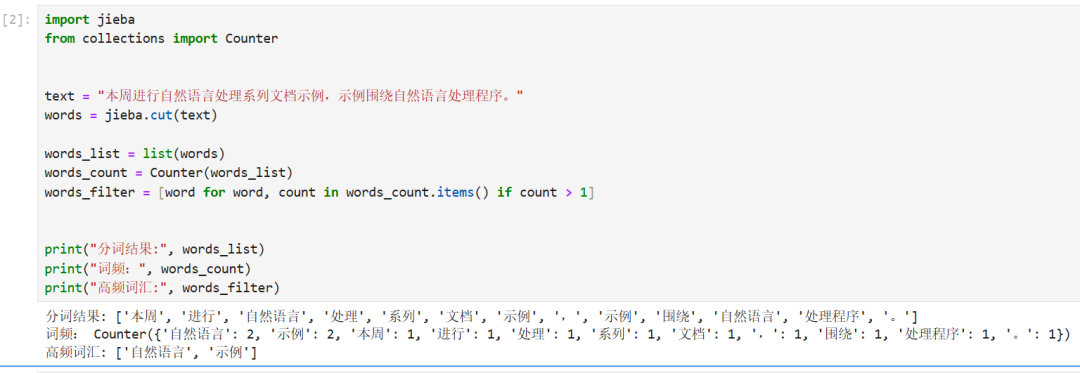
在这里插入图片描述
本文参与 腾讯云自媒体同步曝光计划,分享自微信公众号。
原始发表:2025-08-17,如有侵权请联系 cloudcommunity@tencent.com 删除
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号