
向量列到doubleType的电火花变换
向量列到doubleType的电火花变换
提问于 2019-04-10 19:50:26
我有一个向量类型的列,每个向量中有一个值。我只想得到这个值,并将该列保持为doubleType。
示例输入df:
|testcol|
[1.3]|
[1.2]|
[3.4]|
期望输出df:
|testcol|
|1.3|
|1.2|
|3.4|
我到目前为止的代码是:
remove_vector_func = udf(lambda x: list(x)[0], DoubleType())
ex= ex.withColumn("testcol", remove_vector_func("testcol"))
此代码将运行,但当我试图显示该列时,它会一直抛出错误:
构造ClassDict的预期零参数(用于numpy.dtype)
我在printSchema()中看到,列类型是正确的:
testcol: double (nullable = true)回答 1
Stack Overflow用户
发布于 2019-07-09 13:39:07
您只需要确保lambda函数返回一个与您的UDF返回类型匹配的对象。在这种情况下,需要将对象转换为浮动类型。
代码:
from pyspark.ml.linalg import Vectors
from pyspark.sql.functions import udf
from pyspark.sql.types import DoubleType

ex = spark.createDataFrame([[1.3],
                            [1.2],
                            [3.4]
                           ], ["test"])

from pyspark.ml.feature import VectorAssembler
assembler = VectorAssembler(inputCols=["test"],outputCol="testcol")
ex = assembler.transform(ex)
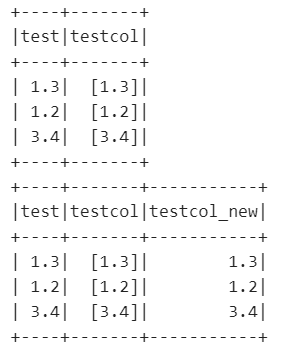
ex.show(5)

# UDF for converting column type from vector to double type
unlist = udf(lambda x: float(list(x)[0]), DoubleType())

ex = ex.withColumn("testcol_new", unlist("testcol"))
ex.show(5)
输出:
页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/55620312
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号