
为什么这个Regexp使用pcre的步骤比Python少99.89%?
为什么这个Regexp使用pcre的步骤比Python少99.89%?
提问于 2018-03-30 19:31:40
我只是在regex101编辑器中构建了这个表达式,但意外地忘记了将其转换为Python风味语法。我不太熟悉这些差异,但我认为它们会很小。他们不是。
Perl/pcre比Python少99.89% (6,377,715对6,565步)
https://regex101.com/r/PRwtJY/3
Regexp:
^(\d{1,3}) +((?:[a-zA-Z0-9\(\)\-≠,]+ )+) +£ *((?:[\d] {1,4}|\d)+)∑([ \d]+)?任何帮助都将不胜感激!谢谢。
编辑
数据源是从PDF中提取的多行txt,结果输出不太完美(您可以看到基本源PDF在这里)。
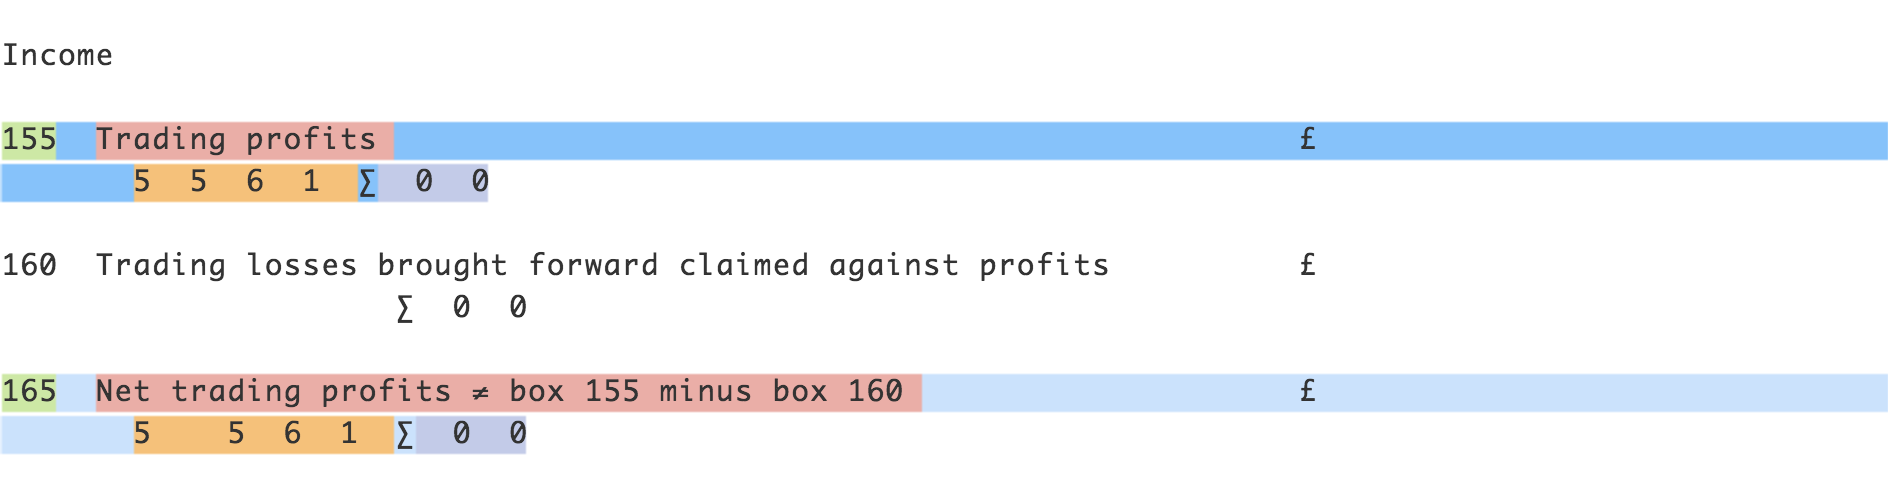
我试图提取特定行的框号、标题和任何存在(填写)的数字。如果您检查上面的链接,您可以看到完整的示例。例如:
下面是Regex101显示正匹配的屏幕截图。最上面的线匹配显示框号(155)、标题(交易利润)和数字(5561)。
Restrictions:
- 理想情况下,当您在PCRE编译器中看到这些值时--在匹配之前或之后几乎没有额外的空格--只提取方框号、标题和值。
- 只有当有一个数字/值被填入时才匹配(例如,在上面的示例中为5561,因此它-框160之后的行不匹配,而是匹配框165)。
- 格式在表单下向下变化,我有一个单独的正则表达式,所以忽略它。
回答 1
Stack Overflow用户
回答已采纳
发布于 2018-03-30 20:53:59
建议:使用新的模块,它支持原子组和拥有式量词。与初始PCRE表达式相比,这减少了所需步骤的大约50% (参见regex101.com上的演示):
^
(\d{1,3})\s++
((?>[^£\n]+))£\s++
([ \d]+)(?>[^∑\n]+)∑\s++
([ \d]+)
要做到这一点,你可以:
import regex as re
rx = re.compile(r'''
    ^
    (\d{1,3})\s++
    ((?>[^£\n]+))£\s++
    ([ \d]+)(?>[^∑\n]+)∑\s++
    ([ \d]+)''', re.M | re.X)

matches = [[group.strip() for group in m.groups()] for m in rx.finditer(data)]
print(matches)
它为除给出的:
[['145', 'Total turnover from trade', '5 2 0 0 0', '0 0'], ['155', 'Trading profits', '5 5 6 1', '0 0'], ['165', 'Net trading profits ≠ box 155 minus box 160', '5 5 6 1', '0 0'], ['235', 'P rofits before other deductions and reliefs ≠ net sum of', '5 5 6 1', '0 0'], ['300', 'Profits before qualifying donations and group relief ≠', '5 5 6 1', '0 0'], ['315', 'Profits chargeable to Corporation Tax ≠', '5 5 6 1', '0 0'], ['475', 'Net Corporation Tax liability ≠ box 440 minus box 470', '1 0 5 6', '5 9'], ['510', 'Tax chargeable ≠ total of boxes 475, 480, 500 and 505', '1 0 5 6', '5 9'], ['525', 'Self-assessment of tax payable ≠ box 510 minus box 515', '1 0 5 6', '5 9'], ['600', 'Tax outstanding ≠', '1 0 5 6', '5 9']]页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/49580317
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号