
与RDD和DataFrame不同的浮点精度
与RDD和DataFrame不同的浮点精度
提问于 2018-01-26 16:04:42
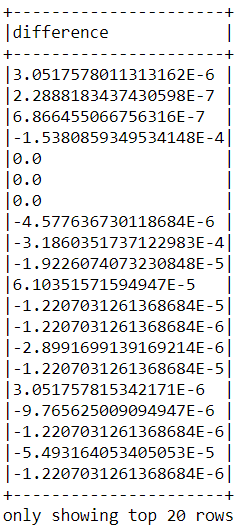
我将RDD更改为DataFrame,并将结果与我使用read.csv导入的另一个DataFrame进行了比较,但浮点精度与这两种方法并不相同。谢谢你的帮助。
我使用的数据来自这里。
from pyspark.sql import Row
from pyspark.sql.types import *
RDD方法
orders = sc.textFile("retail_db/orders")
order_items = sc.textFile('retail_db/order_items')
orders_comp = orders.filter(lambda line: ((line.split(',')[-1] == 'CLOSED') or  (line.split(',')[-1] == 'COMPLETE')))
orders_compMap = orders_comp.map(lambda line: (int(line.split(',')[0]), line.split(',')[1]))

order_itemsMap = order_items.map(lambda line: (int(line.split(',')[1]),
                                           (int(line.split(',')[2]), float(line.split(',')[4])) ))

 joined = orders_compMap.join(order_itemsMap)
 joined2 = joined.map(lambda line: ((line[1][0], line[1][1][0]), line[1][1][1]))

joined3 = joined2.reduceByKey(lambda a, b : a +b).sortByKey()

df1 = joined3.map(lambda x:Row(date = x[0][0], product_id = x[0][1], total  = x[1])).toDF().select(['date','product_id', 'total'])
DataFrame
 schema = StructType([StructField('order_id', IntegerType(), True),
                StructField('date', StringType(), True),
                StructField('customer_id', StringType(), True),
                 StructField('status', StringType(), True)])


 orders2 = spark.read.csv("retail_db/orders",schema = schema)


 schema = StructType([StructField('item_id', IntegerType(), True),
                StructField('order_id', IntegerType(), True),
                StructField('product_id', IntegerType(), True),
                 StructField('quantity', StringType(), True),
                 StructField('sub_total', FloatType(), True),
                 StructField('product_price', FloatType(), True)])


orders_items2 = spark.read.csv("retail_db/order_items", schema = schema)

orders2.registerTempTable("orders2t")
orders_items2.registerTempTable("orders_items2t")

 df2 = spark.sql('select o.date, oi.product_id, sum(oi.sub_total)  \
      as total from  orders2t as o inner join orders_items2t as oi on
      o.order_id = oi.order_id \
      where o.status in ("CLOSED", "COMPLETE") group by o.date,
     oi.product_id order by  o.date, oi.product_id')
是一样的吗?
df1.registerTempTable("df1t")
df2.registerTempTable("df2t")

 spark.sql("select d1.total - d2.total as difference from df1t as d1 inner
 join df2t as d2 on d1.date = d2.date \
 and d1.product_id =d2.product_id ").show(truncate = False)
回答 1
Stack Overflow用户
回答已采纳
发布于 2018-01-26 16:29:39
在转换中忽略精度损失是不一样的。
- Python 根据Python浮点算法的问题与局限性标准实现使用64位表示: 今天(2000年11月)几乎所有的机器都使用IEEE-754浮点算法,几乎所有的平台都将Python浮点数映射到IEEE-754“双精度”。754倍包含53位精度,
- Spark
在使用32位表示中:
FloatType:表示4字节、单精度浮点数.
使用DoubleType可能更接近:
DoubleType:表示8字节双精度浮点数.
但是,如果可预测的行为很重要,那么您应该使用定义良好的DecimalTypes。
页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/48465055
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号