
如何在BigQuery和Python中使用较少的内存来加载数据
如何在BigQuery和Python中使用较少的内存来加载数据
提问于 2019-12-18 02:22:51
有人像这样使用BigQuery吗?
我发现了一些奇怪的东西。
这里有两个例子。
EX 1)
select var1, var2
from table
EX 2)
select strct(var1, var2) as var
from table
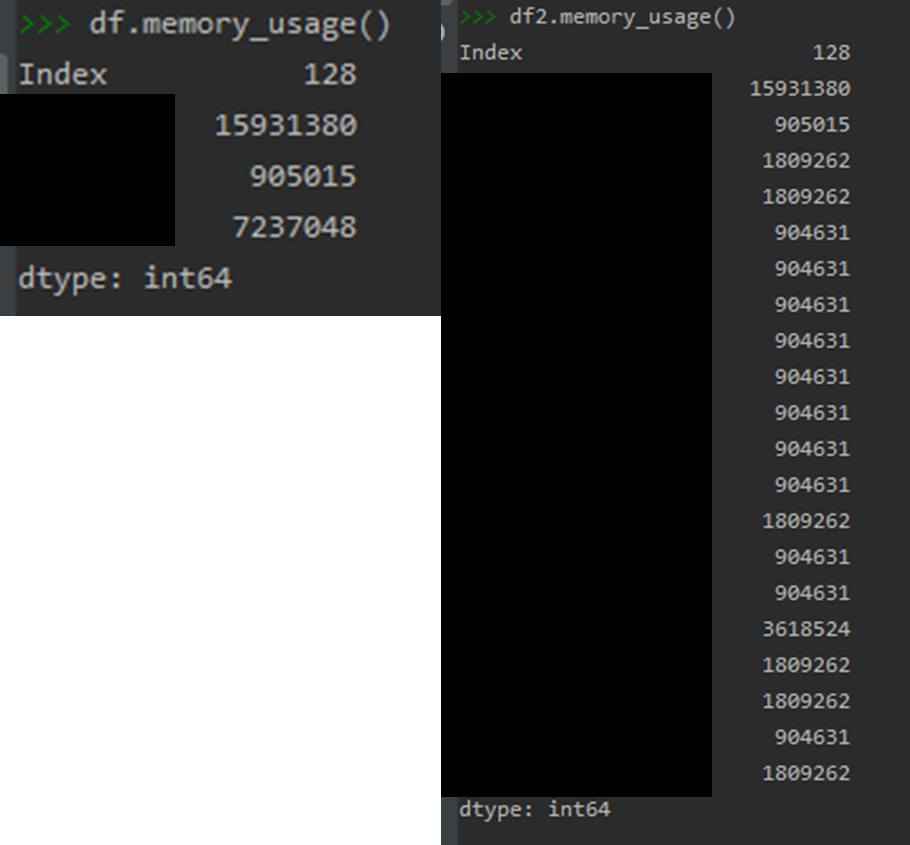
这些结果是相同的,但在Python中不同。
我不知道为什么df,df2使用不同的内存大小。
回答 1
Stack Overflow用户
发布于 2020-01-08 14:58:32
我使用了您提供的示例查询,并使用您提供的信息创建了一个表。我用这个脚本来尝试娱乐:
def query_stackoverflow():
    client = bigquery.Client()
    query_job = """
    select date,
    userid, struct(price, code) as struced_var
    FROM `projectid.dataset.table`
"""
    df = client.query(query_job).to_dataframe()
    print(df)
    print(df.memory_usage())
if __name__ == '__main__':
    query_stackoverflow()
我的产出是:
        date  userid                 struced_var
0  2020-01-07       1  {'price': 10, 'code': 100}
1  2020-01-07       1  {'price': 10, 'code': 100}
2  2020-01-07       1  {'price': 10, 'code': 100}
3  2020-01-07       1  {'price': 10, 'code': 100}
4  2020-01-07       1  {'price': 10, 'code': 100}
5  2020-01-07       1  {'price': 10, 'code': 100}
6  2020-01-07       1  {'price': 10, 'code': 100}
7  2020-01-07       1  {'price': 10, 'code': 100}
8  2020-01-07       1  {'price': 10, 'code': 100}
9  2020-01-07       1  {'price': 10, 'code': 100}

Index          128
date            80
userid          80
struced_var     80
dtype: int64
我也尝试了相同的查询没有结构。我的产出是:
        date  userid  price  code
0  2020-01-07       1     10   100
1  2020-01-07       1     10   100
2  2020-01-07       1     10   100
3  2020-01-07       1     10   100
4  2020-01-07       1     10   100
5  2020-01-07       1     10   100
6  2020-01-07       1     10   100
7  2020-01-07       1     10   100
8  2020-01-07       1     10   100
9  2020-01-07       1     10   100

Index     128
date       80
userid     80
price      80
code       80
dtype: int64
最后,一切都是按预期进行的。在查询中使用结构时,memory_usage返回的列比不使用结构时少1列。这是由合并了价格和代码列的结构造成的。因此,对于struct,我们在memory_usage中看到了3列,而没有struct,我们看到了4列。
我仍然不知道为什么您的查询缺少多个列,但我认为这可能是因为结构将查询的多列组合在一起,并在memory_usage中返回更少的列。无论哪种方式,它都不会显示您是如何将数据加载到BigQuery中的。
页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/59384620
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号