
删除特定列中具有特定值的重复行
删除特定列中具有特定值的重复行
提问于 2020-03-27 15:31:11
我有一个数据框架,我希望删除除一列以外的所有列中重复的行,并选择保留不确定值的行。
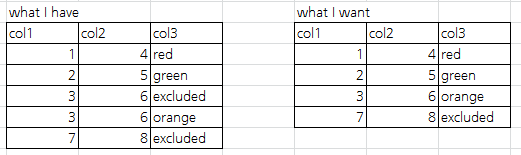
在上面的示例中,除了col3之外,所有列都重复第3行和第4行,所以我只想保留一行。复杂的步骤是我想保留第4行而不是第3行,因为col3中的第3行是“排除”的。通常,我只希望保留没有“排除”的行(重复的行)。
我的实际数据帧中有很多重复的行,其中的2行被复制,其中一行肯定被“排除”了。
以下是可再生产的ex:
a <- c(1,2,3,3,7)
b <- c(4,5,6,6,8)
c <- c("red","green","excluded","orange","excluded")
d <- data.frame(a,b,c)
非常感谢!
更新:或者,删除重复时,只保留第二个观察(第4行)。
回答 5
Stack Overflow用户
回答已采纳
发布于 2020-03-27 15:42:11
具有某些R基的dplyr应该可以用于此:
 library(dplyr)
 a <- c(1,2,3,3,3,7)
 b <- c(4,5,6,6,6,8)
 c <- c("red","green","brown","excluded","orange","excluded")
 d <- data.frame(a,b,c)

 d <- filter(d, !duplicated(d[,1:2]) | c!="excluded")

Result:
  a b        c
1 1 4      red
2 2 5    green
3 3 6    brown
4 3 6   orange
5 7 8 excluded
过滤器将摆脱任何应该排除和不重复的东西。我还在您的示例(‘brown’)中添加了一个none唯一排除的示例来进行测试。
Stack Overflow用户
发布于 2020-03-27 16:02:39
下面是一个循环的示例:
a <- c(1,2,3,3,7)
b <- c(4,5,6,6,8)
c <- c("red","green","excluded","orange","excluded")
d<- data.frame(a,b,c)

# Give row indices of duplicated rows (only the second and more occurence are given)
duplicated_rows=which(duplicated(d[c("a","b")]))

to_remove=c()
# Loop over different duplicated rows
for(i in duplicated_rows){
  # Find simmilar rows
  selection=which(d$a==d$a[i] & d$b==d$b[i])
  # Sotre indices of raw in the set of duplicated row whihc are "excluded"
  to_remove=c(to_remove,selection[which(d$c[selection]=="excluded")])
}

# Remove rows
d=d[-to_remove,]

print(d)

> a b       c
> 1 4      red
> 2 2 5   green
> 4 3 6   orange
> 5 7 8 excludedStack Overflow用户
发布于 2020-03-27 17:38:22
有一种可能性..。我希望它能有所帮助:)
nquit <- (d %>%
  mutate(code= 1:nrow(d)) %>%
  group_by(a, b) %>%
  mutate(nDuplicate= n()) %>%
  filter(nDuplicate > 1) %>%
  filter(c == "excluded"))$code

e <- d[-nquit]页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/60889155
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号