
问题: pandas.DataFrame.mean删除列
问题: pandas.DataFrame.mean删除列
提问于 2022-10-10 09:52:36
我正在和Google Colab合作创建一个神经网络。我导入了dataset并创建了dataframe,但是当我使用函数mean时,它会删除最后的列(从列“res_x4trap”中删除)。我做错什么了?
下面是代码:
import numpy as np
import pandas as pd
import tensorflow as tf
from tensorflow import keras
from tensorflow.keras import layers
from tensorflow import feature_column
from matplotlib import pyplot as plt

# Data collection
filepath = '/content/netdataset.csv'
data = pd.read_csv(filepath, sep=";")
data.set_index('INDEX')

test_df = data.sample(frac=0.2, random_state=1337)
train_df = data.drop(test_df.index)

train_df = train_df.reindex(np.random.permutation(train_df.index)) # shuffle the training set

# Calculate the Z-scores of each column in the training set and
# write those Z-scores into a new pandas DataFrame named train_df_norm.
train_df_mean = train_df.mean()
train_df_std = train_df.std()
train_df_norm = (train_df - train_df_mean)/train_df_std

# Examine some of the values of the normalized training set. Notice that most
# Z-scores fall between -2 and +2.
train_df_norm.head()
在此之前:
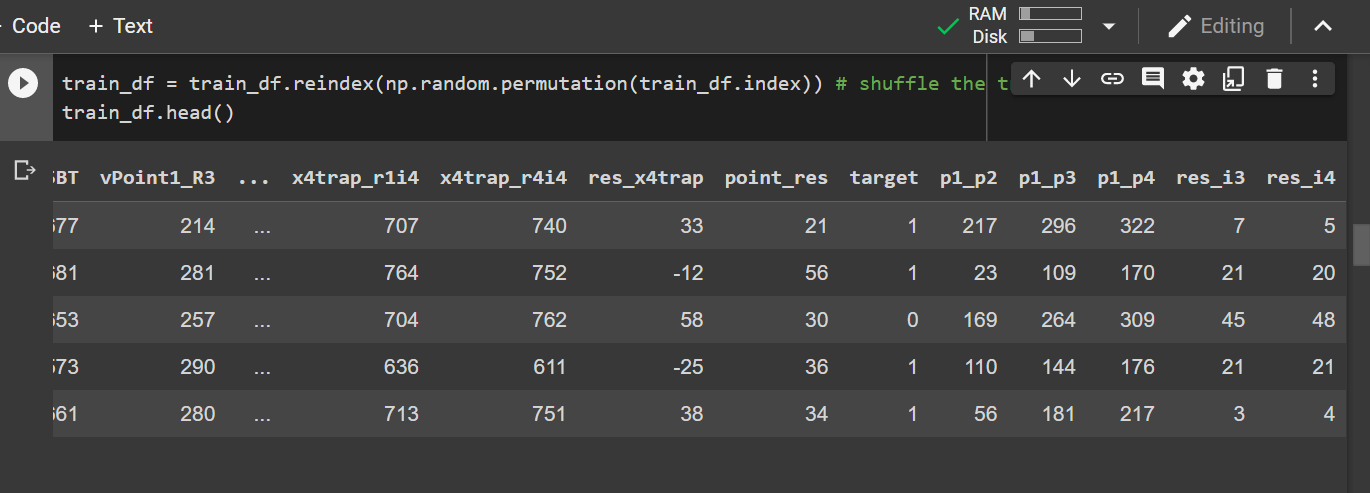
之后:
回答 1
Stack Overflow用户
回答已采纳
发布于 2022-10-31 07:40:42
我遇到了同样的问题,结果我的一列是object类型的,因为有问题的条目,所以熊猫在计算平均值时不知道该怎么做,所以就把它删除了。
因此,使用df.dtypes检查列的d类型
页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/74013060
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号