
检查df列的每一行在列表中的值。
检查df列的每一行在列表中的值。
提问于 2022-02-02 16:34:22
我对dataframe感兴趣的专栏看起来像
names=['nonsoluable water', 'water percentage 98% grade', 'special chemical with grade chlorine', 'name with value']还有其他栏目。这些只是数字/标识符。
如果列中有任何值,则需要检查该列的每一行:
check_for_these = waters, grades, %, chemical如果列有列表中的任何值,我希望它在新列中标记行。
我试过这个:
df['names'].apply(lambda x: any([k in x for k in check_for_these]))但它会产生错误/产生错误的输出。
isin函数还会引发错误:
df['match'] = df["names"].isin(check_for_these)
print(df)
我希望输出像下面给出的图像
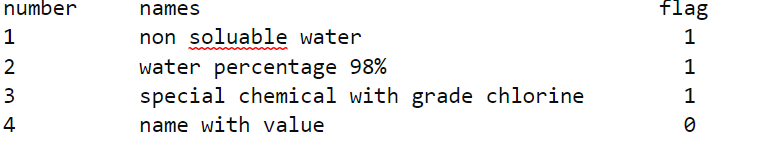
回答 2
Stack Overflow用户
回答已采纳
发布于 2022-02-02 16:57:51
试试这个:
df['flag'] = df['names'].str.contains('|'.join(check_for_these), regex=True, case=False).astype(int)Stack Overflow用户
发布于 2022-02-04 06:59:47
首先,您需要确保名称列中的所有数据都是正确的格式,因此您需要转换所有小写字母,您可以这样做
df['name'] = df['name'].apply(lambda str : str.lower())现在,您可以使用python中的字符串' in‘操作,如果一个字符串是另一个字符串的子字符串,则此操作返回true;这个操作区分大小写,这就是我们关心小写的原因。这个是这样工作的
'hello' in 'all my friends, hello' ----> True
'$' in 'bitcoin is cheap $.$' ---------> True
'Hello' in 'hello world' --------------> False
所以,在你的例子中,你有一个列表
check_for_these = ['waters', 'grades', '%', 'chemical']然后你可以制作你的“真”,“假”价值的熊猫系列
df['names'].apply(lambda str: any([(reqWord in str) for reqWord in check_for_these]))现在您只需执行映射{True : 1,False : 0},并生成标志列,因此解决方案是
df['flag'] = df['names'].apply(lambda str: any([(reqWord in str) for reqWord in check_for_these])).map({True : 1, False : 0})注意:您可以通过执行下一个步骤来省略第一步。
df['flag'] = df['names'].apply(lambda str: any([(reqWord in str.lower()) for reqWord in check_for_these])).map({True : 1, False : 0})页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/70959319
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号