elasticsearch批量写入随机测试数据
原创
原始项目地址 https://github.com/oliver006/elasticsearch-test-data
vim es_test_data.py ,在原始代码上稍微修改,改动后的内容如下
#!/usr/bin/python
# 改动:1去掉了type参数;2改为默认跳过ssl certificate

# pip3 install tornado==6.5.0
# pip3 install nest-asyncio==1.5.1

import nest_asyncio
nest_asyncio.apply()

import json
import csv
import time
import logging
import random
import string
import uuid
import datetime

import tornado.gen
import tornado.httpclient
import tornado.ioloop
import tornado.options

try:
    xrange
    range = xrange
except NameError:
    pass

async_http_client = tornado.httpclient.AsyncHTTPClient()
headers = tornado.httputil.HTTPHeaders({"content-type": "application/json"})
id_counter = 0
upload_data_count = 0
_dict_data = None


def delete_index(idx_name):
    try:
        url = "%s/%s?refresh=true" % (tornado.options.options.es_url, idx_name)
        request = tornado.httpclient.HTTPRequest(url, headers=headers, method="DELETE", request_timeout=240, auth_username=tornado.options.options.username, auth_password=tornado.options.options.password, validate_cert=tornado.options.options.validate_cert)
        response = tornado.httpclient.HTTPClient().fetch(request)
        logging.info('Deleting index  "%s" done   %s' % (idx_name, response.body))
    except tornado.httpclient.HTTPError:
        pass


def create_index(idx_name):
    schema = {
        "settings": {
            "number_of_shards":   tornado.options.options.num_of_shards,
            "number_of_replicas": tornado.options.options.num_of_replicas
        },
        "refresh": True
    }

    body = json.dumps(schema)
    url = "%s/%s" % (tornado.options.options.es_url, idx_name)
    try:
        logging.info('Trying to create index %s' % (url))
        request = tornado.httpclient.HTTPRequest(url, headers=headers, method="PUT", body=body, request_timeout=240, auth_username=tornado.options.options.username, auth_password=tornado.options.options.password, validate_cert=tornado.options.options.validate_cert)
        response = tornado.httpclient.HTTPClient().fetch(request)
        logging.info('Creating index "%s" done   %s' % (idx_name, response.body))
    except tornado.httpclient.HTTPError:
        logging.info('Looks like the index exists already')
        pass


@tornado.gen.coroutine
def upload_batch(upload_data_txt):
    try:
        request = tornado.httpclient.HTTPRequest(tornado.options.options.es_url + "/_bulk",
                                                 method="POST",
                                                 body=upload_data_txt,
                                                 headers=headers,
                                                 request_timeout=tornado.options.options.http_upload_timeout,
                                                 auth_username=tornado.options.options.username, auth_password=tornado.options.options.password, validate_cert=tornado.options.options.validate_cert)
        response = yield async_http_client.fetch(request)
    except Exception as ex:
        logging.error("upload failed, error: %s" % ex)
        return

    result = json.loads(response.body.decode('utf-8'))
    res_txt = "OK" if not result['errors'] else "FAILED"
    took = int(result['took'])
    logging.info("Upload: %s - upload took: %5dms, total docs uploaded: %7d" % (res_txt, took, upload_data_count))


def get_data_for_format(format):
    split_f = format.split(":")
    if not split_f:
        return None, None

    field_name = split_f[0]
    field_type = split_f[1]

    return_val = ''

    if field_type == 'arr':
        return_val = []
        array_len_expr = split_f[2]
        if '-' in array_len_expr:
            (min,max) = array_len_expr.split('-')
            array_len = generate_count(int(min), int(max))
        else:
            array_len = int(array_len_expr)

        single_elem_format = field_name + ':' + format[len(field_name) + len(field_type) + len(array_len_expr) + 3 : ]
        for i in range(array_len):
            x = get_data_for_format(single_elem_format)
            return_val.append(x[1])

    elif field_type == "bool":
        return_val = random.choice([True, False])

    elif field_type == "str":
        min = 3 if len(split_f) < 3 else int(split_f[2])
        max = min + 7 if len(split_f) < 4 else int(split_f[3])
        length = generate_count(min, max)
        return_val = "".join([random.choice(string.ascii_letters + string.digits) for x in range(length)])

    elif field_type == "int":
        min = 0 if len(split_f) < 3 else int(split_f[2])
        max = min + 100000 if len(split_f) < 4 else int(split_f[3])
        return_val = generate_count(min, max)

    elif field_type == "ipv4":
        return_val = "{0}.{1}.{2}.{3}".format(generate_count(0, 245),generate_count(0, 245),generate_count(0, 245),generate_count(0, 245))

    elif field_type in ["ts", "tstxt"]:
        now = int(time.time())
        per_day = 24 * 60 * 60
        min = now - 30 * per_day if len(split_f) < 3 else int(split_f[2])
        max = now + 30 * per_day if len(split_f) < 4 else int(split_f[3])
        ts = generate_count(min, max)
        return_val = int(ts * 1000) if field_type == "ts" else datetime.datetime.fromtimestamp(ts).strftime("%Y-%m-%dT%H:%M:%S.000-0000")

    elif field_type == "words":
        min = 2 if len(split_f) < 3 else int(split_f[2])
        max = min + 8 if len(split_f) < 4 else int(split_f[3])
        count = generate_count(min, max)
        words = []
        for _ in range(count):
            word_len = random.randrange(3, 10)
            words.append("".join([random.choice(string.ascii_letters + string.digits) for x in range(word_len)]))
        return_val = " ".join(words)

    elif field_type == "dict":
        global _dict_data
        min = 2 if len(split_f) < 3 else int(split_f[2])
        max = min + 8 if len(split_f) < 4 else int(split_f[3])
        count = generate_count(min, max)
        return_val = " ".join([random.choice(_dict_data).strip() for _ in range(count)])

    elif field_type == "text":
        text = ["text1", "text2", "text3"] if len(split_f) < 3 else split_f[2].split("-")
        min = 1 if len(split_f) < 4 else int(split_f[3])
        max = min + 1 if len(split_f) < 5 else int(split_f[4])
        count = generate_count(min, max)
        words = []
        for _ in range(count):
            words.append(""+random.choice(text))
        return_val = " ".join(words)

    return field_name, return_val


def generate_count(min, max):
    if min == max:
        return max
    elif min > max:
        return random.randrange(max, min);
    else:
        return random.randrange(min, max);


def generate_random_doc(format):
    global id_counter

    res = {}

    for f in format:
        f_key, f_val = get_data_for_format(f)
        if f_key:
            res[f_key] = f_val

    if not tornado.options.options.id_type:
        return res

    if tornado.options.options.id_type == 'int':
        res['_id'] = id_counter
        id_counter += 1
    elif tornado.options.options.id_type == 'uuid4':
        res['_id'] = str(uuid.uuid4())

    return res


def set_index_refresh(val):

    params = {"index": {"refresh_interval": val}}
    body = json.dumps(params)
    url = "%s/%s/_settings" % (tornado.options.options.es_url, tornado.options.options.index_name)
    try:
        request = tornado.httpclient.HTTPRequest(url, headers=headers, method="PUT", body=body, request_timeout=240, auth_username=tornado.options.options.username, auth_password=tornado.options.options.password, validate_cert=tornado.options.options.validate_cert)
        http_client = tornado.httpclient.HTTPClient()
        http_client.fetch(request)
        logging.info('Set index refresh to %s' % val)
    except Exception as ex:
        logging.exception(ex)


def csv_file_to_json(csvFilePath):
    data = []

    # Open a csv reader called DictReader
    with open(csvFilePath, encoding='utf-8') as csvf:
        csvReader = csv.DictReader(csvf)
        for rows in csvReader:
            data.append(rows)

    return json.dumps(data)


@tornado.gen.coroutine
def generate_test_data():

    global upload_data_count

    if tornado.options.options.force_init_index:
        delete_index(tornado.options.options.index_name)

    create_index(tornado.options.options.index_name)

    # todo: query what refresh is set to, then restore later
    if tornado.options.options.set_refresh:
        set_index_refresh("-1")

    if tornado.options.options.out_file:
        out_file = open(tornado.options.options.out_file, "w")
    else:
        out_file = None

    if tornado.options.options.dict_file:
        global _dict_data
        with open(tornado.options.options.dict_file, 'r') as f:
            _dict_data = f.readlines()
        logging.info("Loaded %d words from the %s" % (len(_dict_data), tornado.options.options.dict_file))

    format = tornado.options.options.format.split(',')
    if not format:
        logging.error('invalid format')
        exit(1)

    ts_start = int(time.time())
    upload_data_txt = ""

    if tornado.options.options.data_file:
        json_array = ""
        if tornado.options.options.data_file.endswith(".csv"):
            json_array = json.loads(csv_file_to_json(tornado.options.options.data_file))
        else:
            with open(tornado.options.options.data_file, 'r') as f:
                json_array = json.load(f)
            logging.info("Loaded documents from the %s", tornado.options.options.data_file)

        for item in json_array:
            cmd = {'index': {'_index': tornado.options.options.index_name}}
            if '_id' in item:
                cmd['index']['_id'] = item['_id']

            upload_data_txt += json.dumps(cmd) + "\n"
            upload_data_txt += json.dumps(item) + "\n"

        if upload_data_txt:
            yield upload_batch(upload_data_txt)
    else:
        logging.info("Generating %d docs, upload batch size is %d" % (tornado.options.options.count,
                                                                      tornado.options.options.batch_size))
        for num in range(0, tornado.options.options.count):

            item = generate_random_doc(format)

            if out_file:
                out_file.write("%s\n" % json.dumps(item))

            cmd = {'index': {'_index': tornado.options.options.index_name}}
            if '_id' in item:
                cmd['index']['_id'] = item['_id']

            upload_data_txt += json.dumps(cmd) + "\n"
            upload_data_txt += json.dumps(item) + "\n"
            upload_data_count += 1

            if upload_data_count % tornado.options.options.batch_size == 0:
                yield upload_batch(upload_data_txt)
                upload_data_txt = ""

        # upload remaining items in `upload_data_txt`
        if upload_data_txt:
            yield upload_batch(upload_data_txt)

    if tornado.options.options.set_refresh:
        set_index_refresh("1s")

    if out_file:
        out_file.close()

    took_secs = int(time.time() - ts_start)

    logging.info("Done - total docs uploaded: %d, took %d seconds" % (tornado.options.options.count, took_secs))


if __name__ == '__main__':
    tornado.options.define("es_url", type=str, default='https://es.demo.com/', help="URL of your Elasticsearch node")
    tornado.options.define("index_name", type=str, default='test_index', help="Name of the index to store your messages")
    tornado.options.define("batch_size", type=int, default=1000, help="Elasticsearch bulk index batch size")
    tornado.options.define("num_of_shards", type=int, default=2, help="Number of shards for ES index")
    tornado.options.define("http_upload_timeout", type=int, default=3, help="Timeout in seconds when uploading data")
    tornado.options.define("count", type=int, default=100000, help="Number of docs to generate")
    tornado.options.define("format", type=str, default='name:str,age:int,last_updated:ts', help="message format")
    tornado.options.define("num_of_replicas", type=int, default=0, help="Number of replicas for ES index")
    tornado.options.define("force_init_index", type=bool, default=False, help="Force deleting and re-initializing the Elasticsearch index")
    tornado.options.define("set_refresh", type=bool, default=False, help="Set refresh rate to -1 before starting the upload")
    tornado.options.define("out_file", type=str, default=False, help="If set, write test data to out_file as well.")
    tornado.options.define("id_type", type=str, default=None, help="Type of 'id' to use for the docs, valid settings are int and uuid4, None is default")
    tornado.options.define("dict_file", type=str, default=None, help="Name of dictionary file to use")
    tornado.options.define("data_file", type=str, default=None, help="Name of the documents file to use")
    tornado.options.define("username", type=str, default=None, help="Username for elasticsearch")
    tornado.options.define("password", type=str, default=None, help="Password for elasticsearch")
    tornado.options.define("validate_cert", type=bool, default=False, help="SSL validate_cert for requests. Use false for self-signed certificates.")
    tornado.options.parse_command_line()

    tornado.ioloop.IOLoop.instance().run_sync(generate_test_data)
写入100w的数据
python es_test_data.py --es_url=https://es.demo.com --count=1000000 --index-name=test-index

日志如下:
[I 250820 14:01:52 bb:54] Trying to create index https://es.demo.com//test-index
[I 250820 14:01:53 bb:59] Looks like the index exists already
[I 250820 14:01:53 bb:272] Generating 1000000 docs, upload batch size is 1000

[I 250820 14:03:26 bb:80] Upload: OK - upload took:     0ms, total docs uploaded:  999000
[I 250820 14:03:26 bb:80] Upload: OK - upload took:     0ms, total docs uploaded: 1000000
[I 250820 14:03:26 bb:305] Done - total docs uploaded: 1000000, took 93 seconds
也可以自定义的field字段
python bb.py --count=10 --index-name=test-index3 --es_url=https://es.demo.com --validate-cert=false --format='name:str,age:int,last_updated:ts,client_ip:ipv4'查询测试
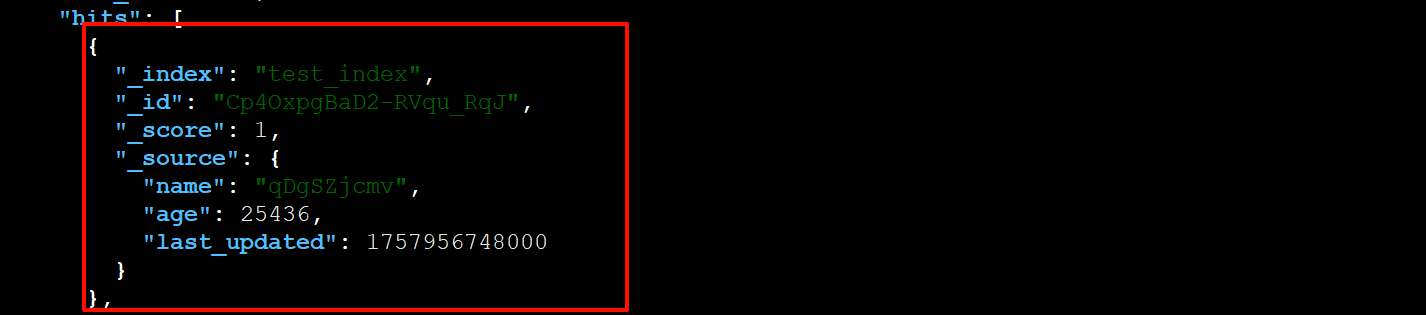
curl -s -H 'Content-Type: application/json' -XPOST https://es.demo.com/test_index/_search | jq .
原创声明:本文系作者授权腾讯云开发者社区发表,未经许可,不得转载。
如有侵权,请联系 cloudcommunity@tencent.com 删除。
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号